CV

Rajesh Rajendran, Staff Data Scientist

7 years building systems, 6+ years building models.

At Avathon I build demand forecasts, inventory policy, production plans and LLM agents for enterprise supply chains. The roots: robotics state estimation, signalling software, then causal inference on rail data.

Read the CVDownload PDF

Bangalore, India

Now, September 2026:multi-echelon inventory optimisation for a mining and industrial operator, a graph against relational database benchmark on a US electric vehicle manufacturer's bill of materials, hiring, and Avathon's new AI Center of Excellence, as one of its three seeding members.

Selected work

Eleven pieces of work, each with the problem, the method and the decision

detect

01

Flagging demand the drivers do not explain

Rolling Bayesian linear regression, Normal-Inverse-Gamma prior, posterior predictive p-values

  • A fixed threshold, like mean plus or minus three standard deviations, does not move with the drivers, so it flags every promotion week. This model sets the expectation from the drivers. Say a promotion week should bring 120 units, give or take 10. If 160 arrive, only the gap the drivers do not explain is flagged.
  • Demand = drivers (promotion, price, seasonality, weather) · weights + Gaussian noise. A zero-centred Gaussian prior on the weights (ridge regression in Bayesian form) plus an inverse-gamma prior on the noise variance is the Normal-Inverse-Gamma prior. It is conjugate, so each rolling-window fit gives the posterior and the posterior predictive, a Student-t, in closed form with no sampling. A two-sided posterior predictive p-value flags drops and spikes.
  • I chose Bayesian regression because its flag comes with a reason. ARIMA, Isolation Forest and deep models can all flag a point, but ARIMA ignores the external drivers and the other two do not say why. Here the posterior weights carry credible intervals, so weight times driver value at the flagged point shows what moved demand. Driver attribution builds on this model.

deployed as a serviceon GCP Cloud Run, in Avathon's demand planning platform

Python, Normal-Inverse-Gamma updating, scikit-learn BayesianRidge, PyMC, FastAPI, Docker, GCP Cloud Run
02

Finding train faults the rules missed

Unsupervised anomaly detection with autoencoders on odometry and ATC signals

  • A rule-based monitor fires only on faults someone already wrote a rule for. Say a rule trips when a signal crosses a fixed limit. A fault that looks odd inside that limit never trips it. I built unsupervised detection on train odometry and ATC (automatic train control) subsystem signals. It reached over 99% recall and surfaced failures the rules missed. I also packaged a statistical fault detection model as a standalone executable for the production fleet management system, where it improved maintenance efficiency by 30%.
  • The models are autoencoders. An autoencoder squeezes a window of signal through a narrow middle layer and then rebuilds it. Trained on normal running, it learns to rebuild normal behaviour well. A window it rebuilds badly is unlike what it trained on, and that reconstruction error is the anomaly score. No failure labels are needed.
  • I chose to learn normal behaviour because railway failures are few and far between. A classifier needs labelled faults, and there are too few to train one. Normal running fills the logs, so learning normal and flagging departures fits the data we have.

Basis Measured by the Alstom team, 2020 to 2023.

in productionon a fleet management system

Python, PyTorch, TensorFlow, autoencoders

explain

03

Naming the driver behind a flagged anomaly

Drop-one-driver Bayesian refits ranked by ΔBIC and Bayes factors, inside a multi-agent planning co-pilot

  • A flag says demand is off, not why. When several drivers move in the same week, seeing which one changed does not settle it. So I drop each candidate in turn (promotion, price, weather, competitor stockout), refit on the anomaly window and rank drivers by how much worse the fit gets. The test demand I generated had a weather shock in only some states.
  • The model is the Bayesian linear regression behind the anomaly detector. Dropping driver j and refitting changes BIC = k ln n - 2 ln L̂. A large rise, ΔBIC, says the window needs that driver, and exp(ΔBIC / 2) approximates the Bayes factor. The posterior coefficient and its credible interval size the effect; weight times driver value gives its contribution at the flag.
  • I attribute with the same Bayesian regression that raises the flag, so one model gives both the detection and the explanation. In a planning co-pilot, a root agent passes a planner's request to anomaly, causal and forecasting agents through structured tool calls under an Observe Orient Decide Act loop, and GPT-4o returns the recommendation with its explanation.

presented internallythe attribution method, at an Avathon monthly all-hands

Python, scikit-learn BayesianRidge, ΔBIC, Bayes factors, LangChain, GPT-4o, structured tool calls

04

Ranking the causes of transit failures

Causal discovery and Causal Bayesian Networks with interventional and counterfactual queries

  • Correlation-based monitoring can say which signals move with a failure, not which one caused it. Say two alarms appear together before most service failures. Correlation ranks them equally, so an engineer checks both. I built a root cause system that ranks causes by probability, so the engineer starts with the most likely one. It went into production on an urban transit fleet, and troubleshooting time fell 86%.
  • Causal discovery learns, from the time-series data logs, a directed graph of which component states influence which. A Causal Bayesian Network gives each node a probability conditioned on its parents. That supports interventional queries, P(failure | do(fault)), which set a component's state and cut the arrows into it. It also supports counterfactual queries: given this failure, would it have happened without that fault?
  • I chose a Causal Bayesian Network because it reaches all three rungs of Pearl's causal hierarchy: association, intervention and counterfactual. Correlation stops at the first, and naming a root cause needs the third. We developed this method as research work, and it became a UAI 2024 paper I co-authored on time-dependent counterfactual root cause analysis. We found no earlier use of the hierarchy for root cause analysis in an industrial setting.

Basis Measured by the Alstom team, 2023 to 2025.

in productionon an urban transit fleet

Python, causal discovery, Causal Bayesian Networks, do-calculus, counterfactual queries

Read the paper

forecast

05

Choosing each series' model on the holdout, not at fit time

WAPE-primary model selection with an event-window gate and a 1.5x degradation cap

  • The pipeline picked each series' model by its in-sample pinball loss at fit time. A score on weeks the model has already seen rewards fitting those weeks, not forecasting new ones. On 69 of 76 series (90.8%), the fit-time winner was not the holdout winner: the in-sample criterion was uncorrelated with holdout accuracy. I retired it and now select on the holdout.
  • WAPE, the primary score, is total absolute error over total demand across the holdout weeks, sum |y - ŷ| / sum y, so big weeks count more. A model must also pass a gate: where a series has at least 3 active event weeks, its event-window WAPE must be at or below 1.2 times its overall WAPE. A 1.5x per-series degradation cap guards against regressions.
  • I also dropped pinball loss at the 85th percentile as the selection score. The forecast feeds a P50 waterfall, so a criterion built for a high quantile was judging the wrong number. Across three pipeline reruns, median holdout WAPE went from 0.574 to 0.529 to 0.451. The cap resolved all 5 major regressions, and all 9 series whose selection changed improved.

Basis Median across 76 weekly retail series, holdout window, single split.

in productionfor a global consumer-devices manufacturer

Python, LightGBM, XGBoost quantile objective, statsmodels ETS and SARIMAX, pandas, parquet

06

Forecasting new products from the ones they replace

Predecessor-successor transition features in gradient-boosted demand forecasters

  • A new PC model starts with almost no order history, but the model it replaces often has a longer one. I mapped each product family to its predecessors, including many-to-many transitions, so a new model can borrow that signal. A family with a single record and no predecessor had nothing to learn from and nothing to borrow, so I marked it not forecastable from history.
  • The forecasters are tree ensembles (XGBoost, LightGBM, CatBoost and Random Forest) with lag features and two lifecycle features: product age and days left in the lifecycle. The one-level predecessor from the transition map is a feature too, so a series with little history carries signal from the product before it. Forecasts run recursively: each month's prediction becomes the next month's lag.
  • I chose to borrow from the predecessor, or from similar product lines, because planners do the same for any new launch. With no history, you make a calculated guess from similar products, yours or the market's. That is analogue forecasting. The same launch problem showed up in a weekly retail forecast at a global consumer-devices manufacturer. One launch overshot about 12 times over (WAPE 11.76), and pre-release clipping zeroed another. I concluded that capped and launch series should be scored by cap correctness and launch-ramp shape, not WAPE.

Basis PC forecast of 80 SKUs over 5 regions; launch series from weekly retail forecasts, holdout window, single split.

deliveredto a global PC manufacturer

Python, pandas, XGBoost, LightGBM, SARIMAX, Prophet, PyTorch LSTM

07

Routing 40,447 spare parts by their demand pattern

Syntetos-Boylan classification feeding a statsforecast model menu

  • Say one part is used a few units every week and another 40 at a time once a year; they need different models. The first design split materials by plant mix. I moved model selection onto each material's own demand pattern and kept plant mix for splitting forecasts. Across 40,447 maintenance and spares materials, quantity share came out smooth 34%, lumpy 22%, intermittent 21% and erratic 18%.
  • Syntetos-Boylan classes use two numbers: ADI, the average gap between periods with demand, and CV², the squared coefficient of variation of the non-zero demand sizes. The standard cut points, ADI 1.32 and CV² 0.49, give four classes. I flagged the 2,888 of 40,447 (7.1%) sitting on a cut point as unstable. Each class routes to a statsforecast menu, with AutoETS, Croston-SBA and TSB among them.
  • A class narrows the menu, but each fit still gets checked. Flat forecasts on seasonal parts showed AutoETS collapsing to a level model. I added a forced seasonal AutoETS entry (ZZA) to the menu. It took one material from MASE 0.77 to 0.51 and another from 1.65 to 1.31. MASE scales error by a naive forecast's error, so below 1 beats naive.

Basis Per-material panel at one site, holdout MASE per series, single split.

shipped to customera mining and industrial operator, where production model selection reads it

Python, statsforecast with AutoETS including forced seasonal ZZA, AutoTheta, Croston-SBA and TSB, conformal prediction intervals, LightGBM, Plotly

decide

08

Judging a forecast by the fill rate it produces

Lognormal lead-time demand, (s,S) policy sweeps and a nested backtest

  • A forecast can look fine on error and still set a reorder point that runs the shelf empty. On one material, a Naive model frozen inside a composite collapsed the forecast band at the second cutoff. The reorder point fell from 3,618 to 489, and fill rate dropped about 54 percentage points. A pre-deployment guardrail caught it before rollout.
  • The forecast gives a P10, P50 and P90 band. I fit a lognormal to it: σ = (ln P90 - ln P50) / 1.2816 from the upper span, because that tail sets the reorder point, and μ = ln P50. A bootstrap over past reservations gives the burst shape inside the lead time. An (s,S) sweep sets s from a service-level grid and S - s from min(EOQ, cap).
  • I selected policies per segment, with per-material overrides only past a 10% margin, because per-material validation fill rate predicted test fill rate at Spearman ρ = 0.06 across 41 keys. The verdict: deploy on 9 smooth series, where test fill rate was 97.7% against the incumbent policy's 74.5% at lower inventory cost, and keep the incumbent on intermittent and lumpy series.

Basis Series at one site; nested split: train to 2024-12, validate on 2025, test on 2026-H1.

decision deliveredto a mining and industrial operator

Python, statsforecast, LightGBM, NumPy and SciPy lognormal fitting, pytest

09

Planning production and freight in one program

A demand forecast feeding a mixed integer linear program for the Master Production Schedule, pack-out and freight mode

  • On average, capacity looked fine: demand averaged 13,033 units a week against 14,409 units a week of pre-build capacity (90.5%). But 23 of 91 weeks ran over the cap, peaking at 80,059 units in the Presidents Day week. Building to each week's demand cannot meet those peaks, so the decision is when to build ahead and how to ship what was built.
  • A demand forecast by SKU, channel, geography and week feeds a mixed integer linear program. It plans the Master Production Schedule and the pack-out together. A yes-or-no one-colour-per-week production constraint is what makes it integer. Weeks-of-supply targets are 12 for channels 1 and 2 and 13 for channel 3. Each week it picks air, fast boat or ocean under a 7-week ocean lead time.
  • To test the planner and not a forecast, I replayed 52 weeks of actual demand through it. On channel 3, about 95% of sales, in one region, the plan cost $508K in freight against $1.53M all air and $763K all fast boat. That equals all ocean: with the pre-build scheduled, ocean could carry the year.

Basis 52-week backcast replay of actual demand, channel 3 (about 95% of sales) in one region; capacity check over 91 weeks of demand.

proof of conceptbackcast replay for a global consumer-devices manufacturer

Python, PuLP, CBC, pandas, XGBoost, SARIMAX

verify

10

Finding and retracting a leak in my own benchmark

Gain-based feature attribution on a global LightGBM, then a leak-free recompute

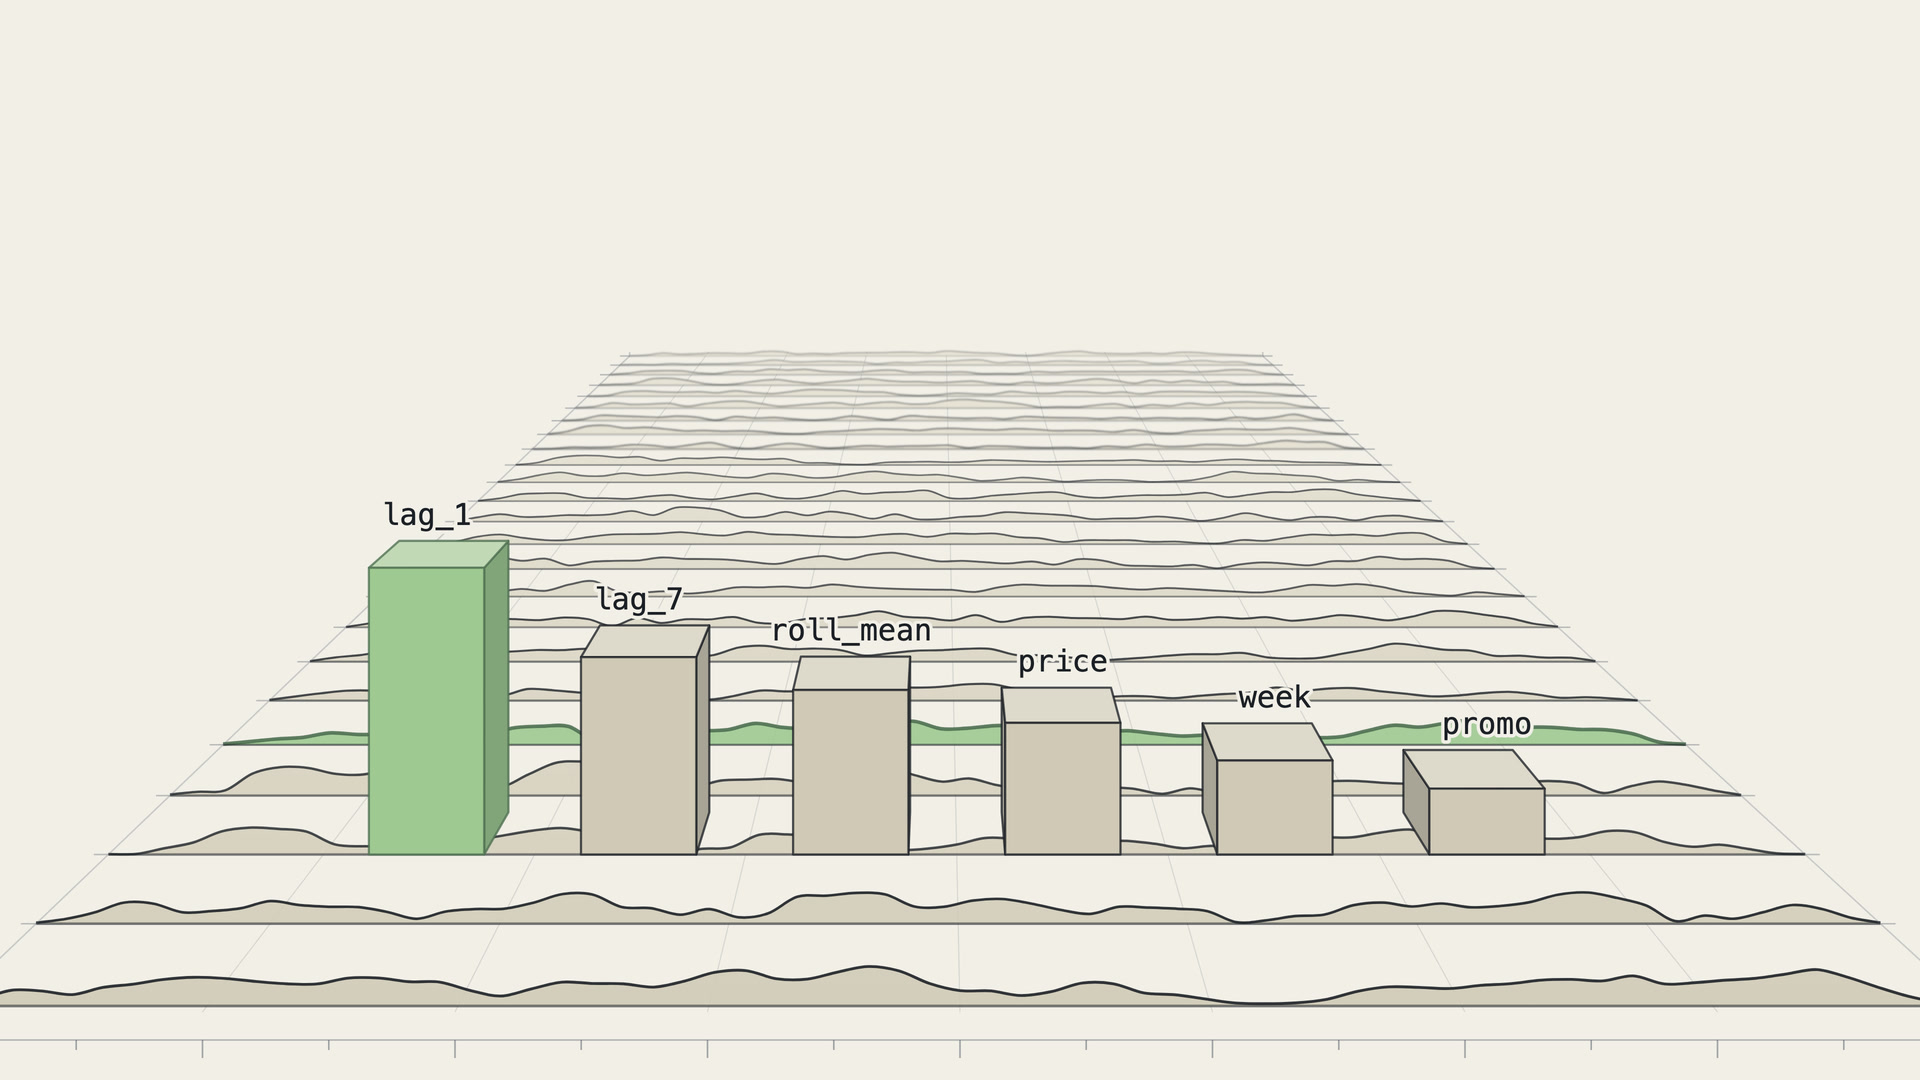
  • A covariate summed over a window that includes the holdout lets the model see the answer. Mine did: the backtest computed total_qty over a window that included the holdout. A feature importance export gave it 68.8% of model gain against lag_1 at 0.08%. The model was estimating each series' scale, not modelling demand dynamics. I now compute covariates only from data before each forecast origin.
  • LightGBM gain importance is each feature's share of the loss reduction from all splits on it. When one aggregate takes most of it and the latest lag gets almost none, the model is reading level, not change. The leak hurt most where lags carry no signal. Rerunning with pre-origin covariates measured it at 9.9 WMAPE points on intermittent demand and 6.2 on lumpy.
  • I retracted the published claim in writing instead of revising it quietly. That claim had LightGBM winning by 23 points. Leak-free, it scored 51.9 WMAPE on intermittent and 69.0 on lumpy, against Croston-Optimized at 62.6 and 70.7. I recomputed all 16 sweep configurations without the leak, and the ranking held. The lesson I wrote down: feature importance is step zero.

Basis Intermittent and lumpy series at one site, holdout backtest.

shipped to customercorrected findings reissued

Python, LightGBM, feature attribution, pandas

orchestrate

11

Assigning ten-digit tariff codes with a written justification

A LangGraph StateGraph agent with hybrid retrieval and a knowledge graph of customs rulings

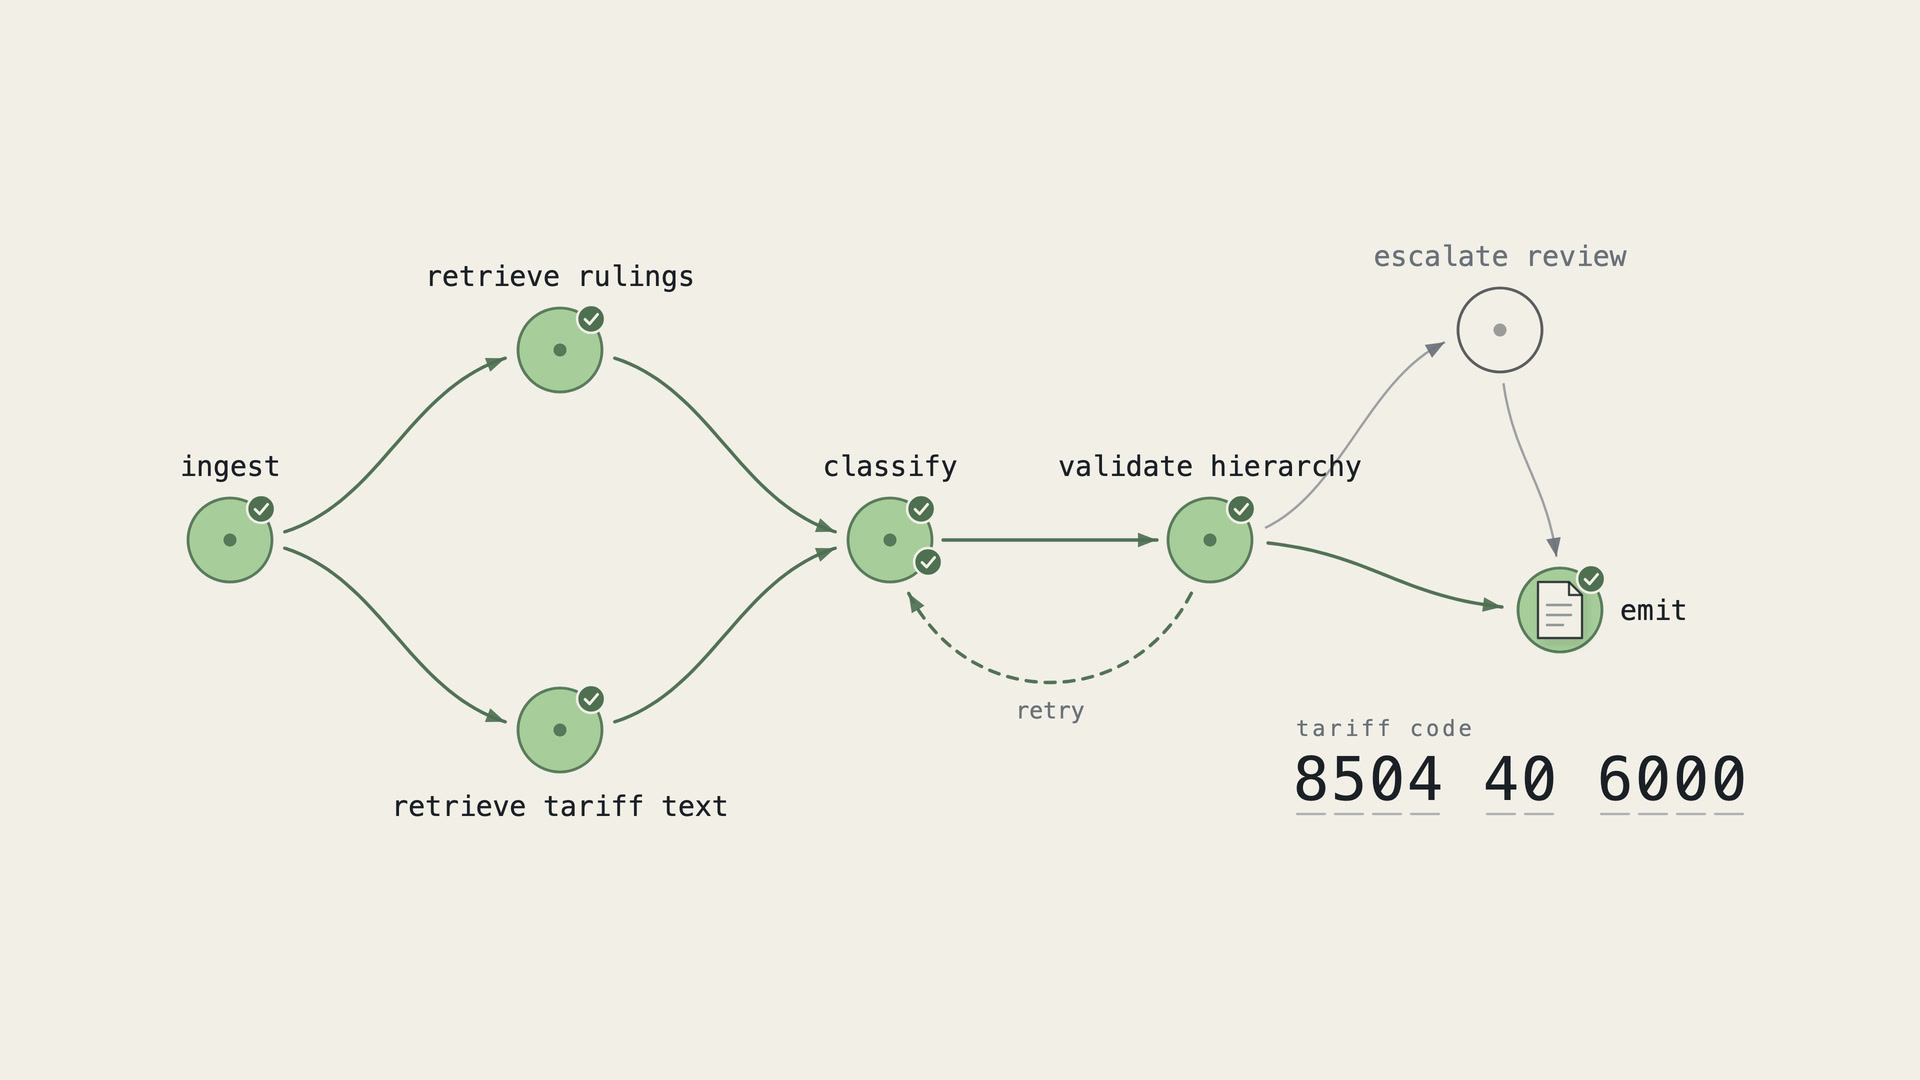
  • A tariff code is a walk down a hierarchy: chapter, heading, subheading, all ten digits. Each step follows the General Rules of Interpretation and thousands of binding rulings, and both change every year. The first version ran the walk inside one ReAct agent with a 3,000-line prompt. I rebuilt it as a LangGraph StateGraph of 7 nodes and 9 edges, so each step can be inspected.
  • An LLM first enriches the sparse part description. Hybrid retrieval then finds candidate headings: BM25 matches exact words, dense embeddings over pgvector and LanceDB match meaning, and combining them catches both. The graph walks the subheadings against a Neo4j knowledge graph of rulings scraped from the CROSS database, records which interpretive rule it applied, and writes a justification with every code.
  • I traced cost and tokens per node in Langfuse. One trace showed Gemini 2.5 Pro spending its whole 4k token allowance on thinking, because the full subheading tree was pasted in up front. A lean prompt with a tool that fetches the tree on demand fixed it, and cost per classification fell from $0.13 to $0.09. I also built a 2,603-item sample from three months of traffic for comparing versions.

Basis Cost per classification on the same classifier before and after the graph optimisation; evaluation sample drawn from three months of live traffic.

in productionat a North American customs brokerage

LangGraph StateGraph, LangChain, Langfuse, Gemini 2.5 Pro, GPT-4o, pgvector, LanceDB, Neo4j, FastAPI, Docker, GCP Cloud Run; an 8B open model fine-tuned on a 2-node SLURM cluster as a cost alternative

More work

Range beyond the eleven, including the software years

  1. Five years of history the filter had hidden

    • An in-house extract filter had silently dropped 51,461 of 60,022 lines, five years of demand history back to 2021-05. Running the complement of the filter recovered all of it.
    • From the recovered 7.97M-row extract I classified 6,148 materials by demand visibility, separating 930 requires-forecast materials holding 60.3% of value from 5,218 order-on-demand materials.

    Shipped to a mining and industrial operator. The incident became a standing rule for the group.

    Python, pandas, SAP AFKO, RESB, MATDOC and MARC tables

  2. The review the green suite could not do

    • A pre-merge review of a new production forecast engine, 50 files and +6,440 lines, returned 18 verified findings, 6 of them critical, and 0 refuted.
    • All 6 critical findings were silent divergences from the source notebook. A passing suite of 78 tests could not see them, because its fixtures were dense and synthetic. The first fix I recommended was a golden-run parity test.

    Gate applied before merge.

    Python, pytest, uv, git worktrees

  3. One network, three levels of demand

    • I built multi-echelon deep learning forecasters in PyTorch: a multi-level LSTM that predicts channel, distribution centre and manufacturing demand jointly rather than as three separate models, across 80 SKUs over 5 geographic regions, their countries and in-country distribution centres.
    • On the same dataset I benchmarked SARIMAX, Prophet, NeuralProphet, gradient boosted trees, Bayesian neural networks and the Chronos foundation model. MAPE for the machine learning tier was 39.9 at shipdate, rising to 61.7 at the deepest disaggregation, against 46.4 to 72.4 for SARIMAX.

    Delivered to a global PC manufacturer.

    PyTorch, LSTM, MLP, torchbnn, XGBoost, LightGBM, CatBoost, Chronos, AutoGluon

  4. Linear programs for the parts that are not forecasting

    • For a bulk logistics operator I delivered set partitioning and facility assignment formulations in PuLP, integrated with an existing Scala scheduler.

    Logistics optimizer integrated.

    Python, PuLP, Scala

  5. Replenishment as a control problem

    • As a proof of concept I framed inventory replenishment as sequential decision making. A simulation API plays out demand, lead time, holding cost and stockout cost week by week; a newsvendor rule and a heuristic reorder rule are the baselines; and a reinforcement learning policy trains against the same simulator.
    • The public demo is on this page. The drawer on the fill rate card runs newsvendor, an (s,S) rule and a Q-learning benchmark on one synthetic part across 500 simulated years, and shows fill rate against cost with its spread.

    Proof of concept and benchmark only, not deployed. The next step is a proof of concept on a live spares catalogue.

    Python, PyTorch, NumPy, simulation API, newsvendor, (s,S), Q-learning

  6. Before the models, the simulators

    • For four years I built simulation and test software for railway signalling. The main piece was a simulator for iVPI-based interlocking systems that replicated logic evaluation, sensor input, relay activation and vital to non-vital parameter exchange, later extended with failover, hot standby and synchronised variable states.
    • I also built automated factory acceptance testing and the protocol interfaces behind it, including a WCF service that exposes data through a SCADA OPC UA server, and a portable diagnostic application that reads datalogs, event faults and snapshots off a train car ATC module over direct serial and Ethernet TCP/IP.

    Shipped inside Alstom Transport, 2015 to 2020.

    C++ with the Microsoft Foundation Class framework, C#, object-oriented design, socket programming, WCF, SCADA OPC UA

Method

Three rules, each backed by a card above

  1. Select on the holdout.

    A model earns its place on data it has not seen. When the fit-time winner and the holdout winner disagreed on 69 of 76 series, I retired the fit-time criterion.

    See card 05
  2. Retract in public.

    When I find an error in my own published result, I say so in writing and recompute. The covariate leak in my benchmark was worth 9.9 WMAPE points on intermittent demand, so I retracted the claim and reran all 16 configurations.

    See card 10
  3. Judge by the decision.

    I score a forecast by the inventory it produces. On the spares work that meant test fill rate and cost, and the incumbent policy stayed on the intermittent and lumpy series.

    See card 08
Rajesh Rajendran

About

Rajesh Rajendran

I studied electronics and instrumentation in Chennai and process automation at TU Dortmund. Then came state estimation for humanoid robots at the German Aerospace Center, and MATLAB simulations for a cancer diagnostic device at Blue Triangle.

At Alstom I wrote railway signalling simulators, then turned to the data: anomaly detection on train telemetry, and a causal root cause system that became a UAI 2024 paper. I was a founding member of a data science team that grew to 20.

At Avathon I forecast demand across a 40,447-material spares catalogue, judge inventory policy by fill rate, and plan production and freight with mixed integer programs. I built a proprietary tariff classification agent now in production, and Bayesian anomaly detection on Cloud Run under a multi-agent planning co-pilot. I fine-tuned an 8B model on a 2-node SLURM cluster as a cost alternative to frontier models. I recruited five engineers, run weekend AI workshops and brought Claude Code into the team.

The journey continues: I am one of three seeding members of Avathon's AI Center of Excellence in Bangalore, set up in August 2026 for Physical AI and frontier models in autonomous industrial operations, and I am reading reinforcement learning.

Timeline

Every role, 2012 to now

  1. Feb 2025 to present

    Staff Data Scientist, Avathon (formerly SparkCognition)

    Demand forecasting, inventory policy, production and freight planning, and LLM agents for enterprise supply chain.

    • Built the SAP MM data foundation for a mining and industrial operator: 36 parquet tables, 130M+ rows, 15 plants and about 5.7 years of history.
    • Defined the Clear-to-Build layer for a US electric vehicle manufacturer: bill of materials explosion, probabilistic ETA, runout projection and a cutover readiness score, taken to a CEO-level review.
    • Fine-tuned an open 8B model on a 2-node SLURM cluster as a cost alternative to frontier models.

    Bangalore, India

  2. Apr 2023 to Feb 2025

    Data Scientist Sr, Alstom Transport

    Causal root cause analysis for urban transit failures, and anomaly detection on real-time transit data with Bayesian networks and statistical process control.

    Bangalore, India

  3. Jan 2020 to Mar 2023

    Data Scientist, Alstom Transport

    Anomaly detection on train odometry and ATC telemetry, and log analytics on Spark with Scala that reduced failure detection time by 53%.

    Bangalore, India

  4. Apr 2018 to Jan 2020

    Software Architect, Alstom Transport

    Diagnostic and simulation tools for train control subsystems in C++ and C#, including a portable diagnostic application for the ATC module and a shared signalling layout editor.

    Bangalore, India

  5. Sep 2015 to Mar 2018

    Software Designer, Alstom Transport

    Simulators and automated factory acceptance testing for railway signalling equipment.

    Bangalore, India

  6. Jul 2014 to Jul 2015

    Product Engineer, Blue Triangle Innovations

    MATLAB simulations supporting the prototyping of a cancer diagnostic device.

    Ruhr Region, Germany

  7. Dec 2012 to Jun 2014

    Research Assistant, German Aerospace Center (DLR)

    State estimation of the under-actuated degrees of freedom in humanoid robots, in MATLAB and Simulink.

    Munich, Germany

  • M.Sc. Process Automation, Technical University of Dortmund, Germany2010 to 2013
  • B.E. Electronics & Instrumentation, MIT, Anna University, India2006 to 2010

Recognition

A paper, a seeding membership, two awards

  • PaperUncertainty in Artificial Intelligence (UAI), 2024, Barcelona

    Industrial-Grade Time-Dependent Counterfactual Root Cause Analysis through the Unanticipated Point of Incipient Failure

    Co-author. The paper sets out the causal method behind the root cause card above.

  • MembershipAvathon, Aug 2026, Bangalore

    Seeding member, AI Center of Excellence

    One of three seeding members of the centre, announced on 27 August 2026 for research and development on Physical AI and frontier models for autonomous industrial operations. The announcement confirms the centre; the membership is my own statement.

    Read the announcement
  • AwardAlstom, Mar 2024

    World Class Expert

    Recognised for developing data solutions.

  • AwardAlstom, Aug 2023

    Winner, SoftWar 2.0

    Applied AI to estimate odometry system tuning parameters. I drove the product design and the presentations.

CertificationsMachine Learning Specialization, DeepLearning.AIFoundations of Causality, causaLensMathematics for Machine Learning and Data Science, DeepLearning.AIData Science Specialization, Johns Hopkins University

Teaching

Trainings, workshops and white papers

I teach as much as I build. At Alstom I owned the causal inference methodology and presented it to cross-functional teams.

At Avathon I run the weekend AI workshops for colleagues who do not work in AI. I brought Claude Code into the team by researching each release and showing the team how to work with it, and I write internal white papers on what we learn.

Stack

What I build with

Forecasting

  • statsforecast
  • AutoETS
  • AutoTheta
  • Croston-SBA
  • TSB
  • SARIMAX
  • Prophet
  • Chronos
  • conformal prediction
  • WAPE
  • MASE

Machine learning

  • LightGBM
  • XGBoost
  • CatBoost
  • scikit-learn
  • PyTorch
  • LSTM
  • autoencoders

Causal and Bayesian

  • Causal Bayesian Networks
  • causal discovery
  • do-calculus
  • PyMC
  • Normal-Inverse-Gamma updating
  • CausalImpact

Agents and retrieval

  • LangGraph
  • LangChain
  • Langfuse
  • pgvector
  • LanceDB
  • Neo4j
  • hybrid BM25 and dense retrieval

Decisions and serving

  • (s,S) policy
  • newsvendor
  • PuLP
  • FastAPI
  • Docker
  • GCP Cloud Run
  • Airflow
  • Python
  • SQL

ReadingSutton and Barto, through the University of Alberta reinforcement learning specialization.

The full list is on the CV page.

Contact

Talk to me

I am open to staff and principal level applied science roles, research collaboration on causal and probabilistic forecasting, and consulting on supply chain AI.

Read the CVDownload PDF

Code I write for learning is on GitHub.

Finding train faults the rules missed: the working

Illustrative reconstruction on synthetic data.

Ranking the causes of transit failures: the working

Illustrative reconstruction on synthetic data.

Choosing each series' model on the holdout, not at fit time: the working

One synthetic part, mechanism demo. Not the 76-series portfolio quoted above.

Judging a forecast by the fill rate it produces: the working

One synthetic part, mechanism demo. Not the production fill rate result quoted above.

Assigning ten-digit tariff codes with a written justification: the working

Scripted trace. Node topology is real; per-step tokens, latency and cost are chosen to land on the measured $0.13 and $0.09 totals.